Reddit monitoring: 125 posts, 7 matches, 1 worth answering
Which Reddit monitoring tools are left in 2026, how an AI agent watches five subreddits and reads each match, and what two rounds on 11 October 2026 found.
Elias Auer · Researcher, Scalebrowser
Published Oct 13, 2026 · 8 min read
Short answer
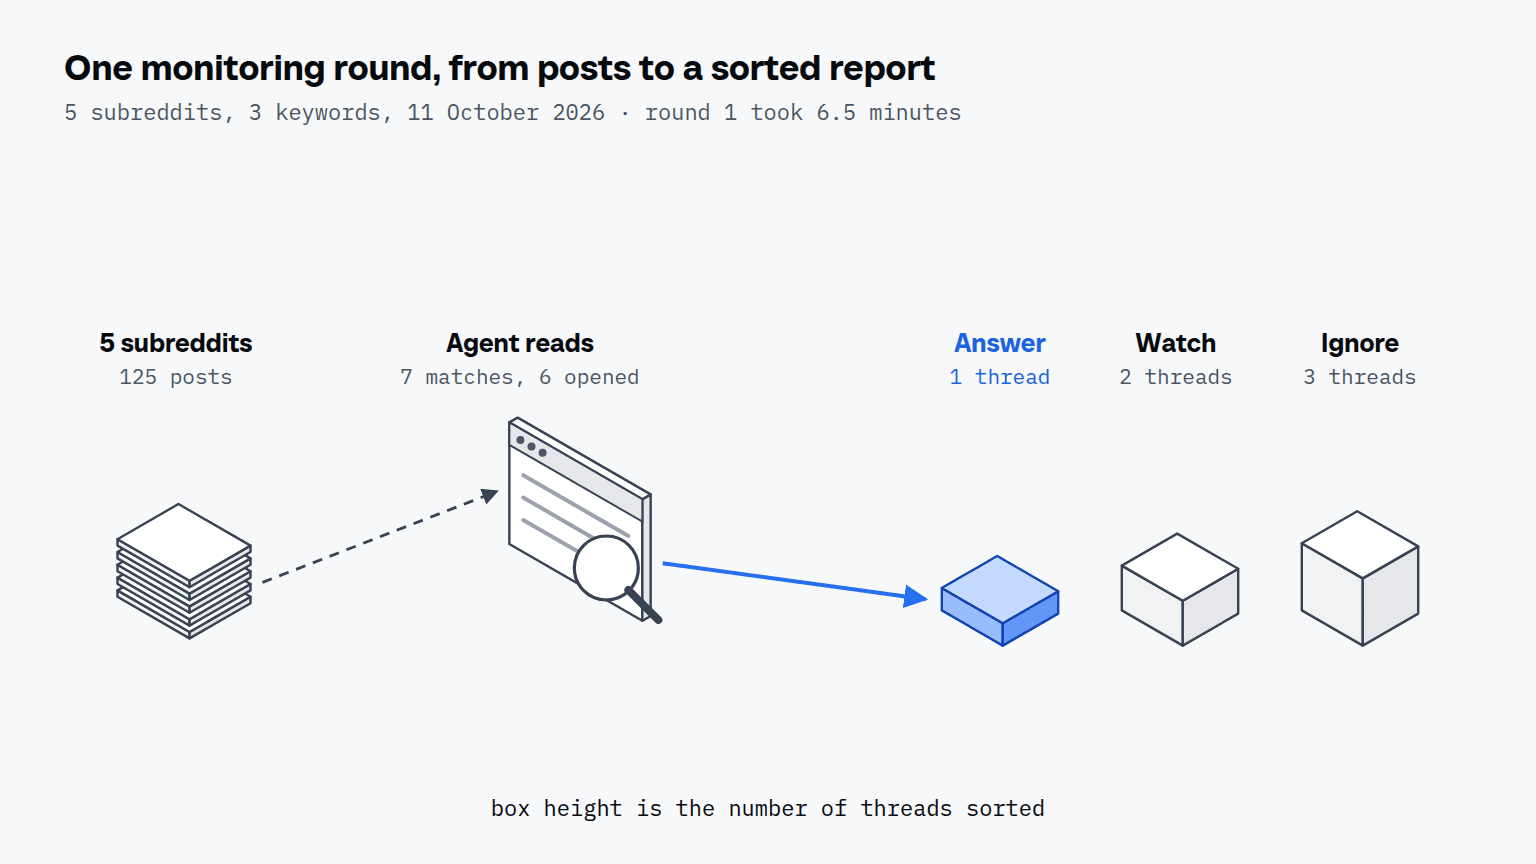
On the evening of 11 October 2026 an agent opened the newest posts of five subreddits and looked for three phrases: "browser agent", "captcha" and "MCP". The first round took 6.5 minutes and 58 tool calls, and 7 of the 125 posts it scanned held one of the phrases. None held "browser agent". The second round, 400 seconds later, took 2.5 minutes and found the same 7.
The rest of this article is what such a round costs, what it hands back and how often to run it.
What is Reddit monitoring?
Reddit monitoring is watching subreddits and keywords and being told when something matters. It comes in three kinds:
- Keyword alerts: a service watches Reddit for your words and emails you each hit.
- Dashboards: a service collects posts and shows counts, topics and trends for you to browse.
- An agent that reads: a browser the agent drives opens each new post, reads the thread and says what it makes of it.
The first two tell you something was said. The third tells you whether it needs you.
Which Reddit monitoring tools are left in 2026?
We could read the pricing pages of two keyword tools, F5Bot and Syften, on 11 October 2026, and the well-known dashboard GummySearch is closed.
| Tool | What it watches | Alerts | Price |
|---|---|---|---|
| F5Bot | Reddit, Hacker News and Lobsters | email, plus Slack, Discord and feeds on the top plan | 0 USD; 9.99 USD a month for 20 keywords; 49.99 USD a month for 200 |
| Syften | Reddit and many other sites, forums and feeds | email, Slack, RSS, API, webhook | 29.95, 49.95 or 119.95 USD a month; MCP on the top plan |
| GummySearch | closed for new sign-ups on 30 November 2025 | not available | |
| An agent in a signed-in browser | any subreddit you choose, read in full | a report you ask for | 19 EUR a month on Scalebrowser Start |
F5Bot says it checks "every few minutes", so an email can reach you faster than any schedule an agent runs on. What it can't do is read the thread and tell you which of 6 hits is a question you could answer.
Why did GummySearch close?
GummySearch closed because of Reddit's API rules. Its closing note of 30 November 2025 says: "we're shutting down to comply with Reddit's API policies, which forbid commercial applications". New sign-ups stopped that day, subscribers keep access until the end of their billing period, up to one year, and lifetime-deal holders until 30 November 2026. Any tool built on the Reddit API as a commercial product stands where GummySearch stood: Reddit's developer help says it needs permission through App Review, and a contract before Reddit data powers a commercial product.
How does an AI agent monitor Reddit?
An agent monitors Reddit by doing, on a schedule, what you would do with a cup of coffee: open the new posts, read the ones that matter and sort them. In steps:
- Record the round once. You walk the agent through the five subreddits one time, and the steps are stored as a routine.
- It replays on a schedule. Each run opens the new posts of each subreddit in an agent browser on duty, a browser that is already signed in.
- It looks for your words. Every post whose text holds one of your keywords is a match. Our 7 were 1 in a title and 6 in the post text the page returned, and "captcha" counted inside "reCAPTCHA".
- It opens each match and reads the thread. The thread itself, not the headline.
- It sorts the match into answer, watch or ignore, with one line of reason.
- It drafts the answer for the ones to answer. You decide what gets posted.
The recording is one of 3 workflow tools in Scalebrowser: workflows record a stretch of agent work and replay it later, finding each element again on the page as it is and drawing a fresh rhythm for each profile.
Our two rounds didn't use a stored routine. An agent walked the route by hand twice and stopped at the sort: it drafted no answer. The second round was faster because Reddit remembered the sort order of each community and listed them under recently visited. A recorded routine is the next step, and we haven't timed one yet.
How is this different from a Reddit MCP server?
A Reddit MCP server answers when you ask, and monitoring asks for you every morning. With a Reddit MCP server you type "what did r/SaaS say about pricing pages", and the agent goes and reads. A monitor has the question built in, runs without you, and only speaks up when a match turns up. The same shape works outside Reddit: a Marketplace deal alert replays one saved search and sends you only the new listings.
How often should the agent check?
Check each subreddit often enough that no more than 25 new posts arrive between two checks, which in our run meant every 4 hours for r/ClaudeAI and once a week for r/webscraping. The age of the 25th newest post tells you the interval.
| Subreddit | Age of the 25th newest post | Check every |
|---|---|---|
| r/ClaudeAI | 4 hours | 4 hours |
| r/SaaS | 6 hours | 6 hours |
| r/AI_Agents | 8 hours | 8 hours |
| r/LocalLLaMA | 10 hours | 10 hours |
| r/webscraping | 9 days | once a week |
A round of all five took 2.5 minutes and 18 tool calls once the route was known, after 6.5 minutes and 58 tool calls the first time. Checking r/ClaudeAI every 4 hours is 6 rounds a day, about 15 minutes of agent time. The two rounds, 6.7 minutes apart, differed by 2 new posts in 125, and neither held a keyword; the list in r/ClaudeAI draws only the posts in view, so a round can miss one between two others, and that is open.
What does a morning report look like?
A morning report from our run of 11 October 2026 held 6 threads: 1 to answer, 2 to watch and 3 to ignore, each with one line of reason. The agent opened 6 of the 7 matched posts and sorted each one. Titles are paraphrased and no author is named.
| Class | Thread, paraphrased | Subreddit | Reason |
|---|---|---|---|
| Answer | When to switch from plain HTTP requests to a real browser, with 403s and CAPTCHAs in the way | r/webscraping | The asker wants exactly this; 2 days old, and two replies already say requests first |
| Watch | Infrastructure frameworks for agents, with sandbox and MCP in the list | r/AI_Agents | Replies say the sandbox and auth contract is the missing piece |
| Watch | A prototype that ships scrapers as JSON manifests | r/webscraping | A neighbouring tool and no question yet; its 21 comments did not come back in the read, so they are unread |
| Ignore | A reCAPTCHA v3 write-up with a repository link | r/webscraping | No question |
| Ignore | Claude saving money on flights through a booking connector | r/AI_Agents | A travel anecdote |
| Ignore | A student asking how to use skills and MCP with coding agents | r/AI_Agents | Generic coding workflow, already answered |
Reading and sorting the 6 threads took 4.3 minutes and 32 tool calls, about 6 of them no-ops or refusals such as a covered link. The agent reads, and you decide: the one thread to answer is a draft for you to rewrite or drop, and the thread whose comments didn't come back says "unread" instead of a guess. Whether a draft may name your product at all depends on the subreddit, and which subreddits limit self-promotion is the map we built before posting anything.


Scalebrowser gives each agent its own isolated browser with a persistent identity, on your own machine, so a run stays signed in, handles the captcha and finishes without anyone watching it.
See how Scalebrowser does itWhat lands with you is that list, 6 lines, and not the 125 posts behind it.
Can the agent replace a recorded routine with RPA?
A recorded agent routine does the work a classic RPA bot does, and it doesn't carry what a bot carries: the exact elements and timings of the recording. Classic RPA replays what was recorded. A Scalebrowser routine stores none of that, and the workflows documentation gives the reason: a stored element reference is dead the moment the page changes, so the routine describes each element by role and accessible name and finds it again on the page as it is. Typed text becomes a named slot and no timing is stored. For Reddit that is the difference between a routine that survives a change to the new-posts list and one that clicks where the old button was; routines instead of classic RPA compares the two.
Where does the browser run?
The browser runs on your own machine, so the routine reads Reddit from an account that is already signed in there. An agent with a standing browser costs 19 EUR a month on Scalebrowser Start, for one browser at a time on one machine, with unlimited profiles. The overview of use cases lists the other jobs, and repeat work is the one this article is.
Run it on your own machine
Seven days to try it with your own agents on your own sites. Starting the trial needs a card.
Written by
Elias Auer
Researcher, Scalebrowser
Researcher at Scalebrowser, the browser layer for AI agents that runs on your own machine. Measures what a web page can observe about a browser, compares it with a real Chrome on the same machine and publishes the numbers, including the ones that went against us.
All articles by Elias Auer